Zara Ludwig · 1 October 2026
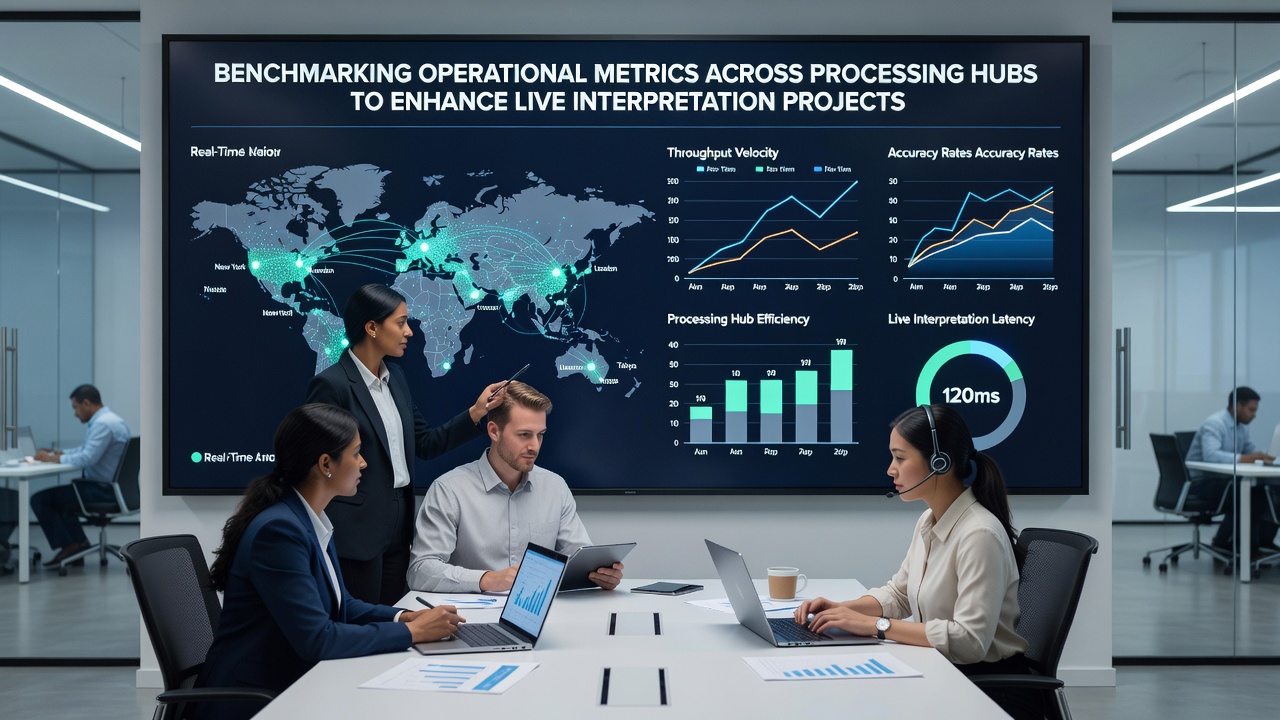
Benchmarking Operational Metrics Across Processing Hubs to Enhance Live Interpretation Projects
Processing hubs form the backbone of live interpretation projects where real-time data streams require rapid analysis and output generation, and benchmarking operational metrics provides the structured comparison needed to identify performance gaps across multiple sites. Teams track variables such as latency, throughput, error rates, and resource utilization because these figures reveal how efficiently each hub converts incoming signals into usable interpretations.
Core Components of Operational Metrics
Latency measures the time between data arrival and initial output, while throughput tracks the volume of data processed within a defined window. Error rates capture inaccuracies in interpretation results, and resource utilization monitors CPU, memory, and network loads during peak operations. Researchers compile these indicators into standardized scorecards that allow direct comparisons between facilities located in different regions.
Studies conducted by academic institutions show consistent patterns when hubs adopt uniform measurement protocols. One project coordinated across North American and European centers found that aligning clock synchronization methods reduced average latency variance by 18 percent within six months. Such alignment proves essential because interpretation projects often integrate outputs from several hubs simultaneously.
Benchmarking Frameworks in Practice
Organizations establish benchmarking frameworks by first defining baseline conditions for each metric, then running controlled test loads that simulate typical live interpretation workloads. These tests run at scheduled intervals so operators can detect drift before it affects project timelines. Data collected during October 2026 trials at multiple facilities highlighted how seasonal increases in network traffic influenced throughput stability, prompting adjustments to routing configurations.
Industry groups publish reference datasets that participating hubs use to calibrate their own measurements. The approach draws from guidelines issued by bodies such as the National Institute of Standards and Technology, which supplies detailed procedures for performance evaluation in distributed computing environments. Teams apply these procedures while maintaining local variations that reflect specific hardware configurations.
Integration with Live Interpretation Workflows
Live interpretation projects depend on continuous data flow, and benchmarking helps teams pinpoint which hubs deliver the most reliable results under varying load conditions. When metrics indicate rising error rates at one location, project managers can reroute portions of the workload to alternate sites that demonstrate stronger stability. This redistribution occurs without interrupting the overall interpretation pipeline.
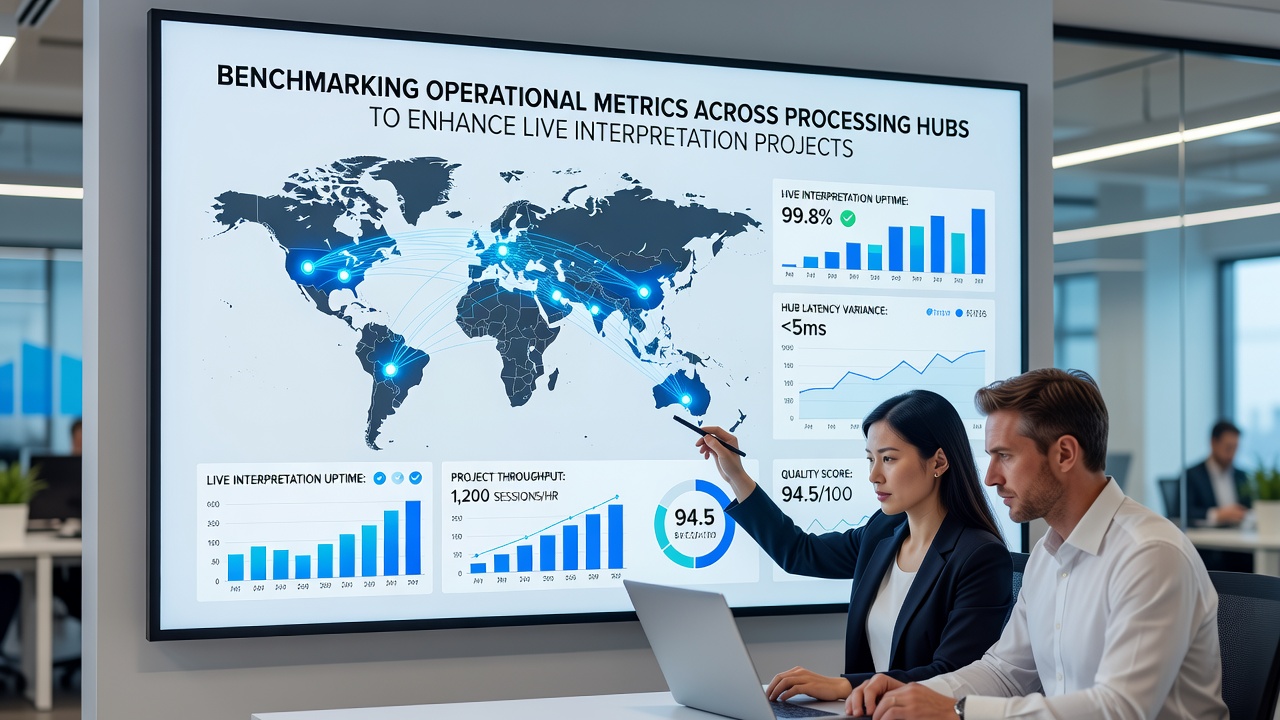
Engineers often examine correlations between resource utilization and interpretation accuracy because high utilization sometimes precedes drops in output quality. Reports from collaborative research networks indicate that maintaining utilization below 75 percent of peak capacity correlates with sustained accuracy levels above established thresholds. Operators therefore schedule maintenance windows based on these observed relationships rather than fixed calendars.
Regional Variations and Data Sources
Facilities in different geographic areas encounter distinct environmental and regulatory factors that influence metric values. Australian research centers, for example, have documented how ambient temperature fluctuations affect cooling system demands and subsequent energy metrics. Canadian studies similarly track how regulatory requirements on data residency shape network routing decisions and resulting latency figures.
These regional datasets feed into broader benchmarking exercises that compare performance across continents. Participants exchange anonymized summaries through secure repositories so each hub can position its results relative to peers without exposing proprietary details. The process supports incremental improvements because operators identify specific areas where their metrics lag behind comparable sites.
Conclusion
Benchmarking operational metrics across processing hubs supplies the quantitative foundation required to refine live interpretation projects on an ongoing basis. Consistent application of standardized measurements enables teams to adjust workloads, optimize resource allocation, and maintain output quality even as project demands evolve. Continued collection of comparable data from diverse locations will further strengthen these evaluation practices in the years ahead.